Abstract
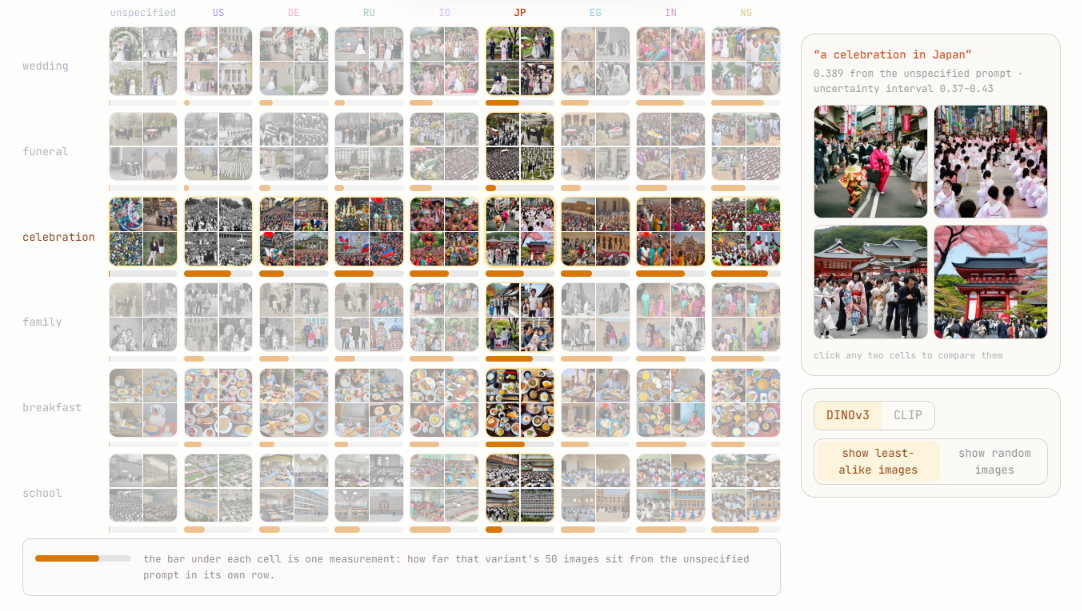
Text-to-image (T2I) models generate complex visual content from textual prompts by learning associations between textual and visual concepts. These associations shape the model's assumptions about the world. When a prompt leaves details unspecified, the model relies on its assumptions to resolve the gaps. Some of these assumptions appear more often in the model output than others, reducing the model’s diversity and sometimes reflecting harmful biases [1, 2, 3]. Consider a wedding scene. Its visual representation may differ depending on whether the wedding takes place in Japan, India, or the United States, including differences in people’s appearance and the surroundings. A prompt such as “a wedding in Japan” specifies the geographic context but still leaves the visual details for the model to resolve based on its assumptions about that country. What details does the model assume for each country? And what happens when the country itself is left unspecified? Do the model assumptions align similarly with different countries, or are they skewed toward some more than others? In this article, we make these geographic assumptions explorable across different T2I models. We study how they appear when geographic context is specified or unspecified, what semantic concepts they reflect, and whether they arise before or during image generation. Through experiments with Stable Diffusion 2.1 [4] we further experiment, for this particular model, how they respond to stronger prompt guidance, and when they become difficult to change during denoising.
Citation
Giray Unlu,
Amal
Alnouri,
Ahmed
Mansour,
Andreas
Hinterreiter,
Marc
Streit
Exploring The Geographic Assumptions in Text-to-Image Models with Underspecified Prompts
VISxAI: 9th Workshop on Visualization for AI Explainability, IEEE VIS 2026,
2026.
BibTeX
@article{,
    title = {Exploring The Geographic Assumptions in Text-to-Image Models with Underspecified Prompts},
    author = {Giray Unlu and Amal Alnouri and Ahmed Mansour and Andreas Hinterreiter and Marc Streit},
    journal = {VISxAI: 9th Workshop on Visualization for AI Explainability, IEEE VIS 2026},
    url = {https://t2i-geo-assumptions.jku-vds-lab.at},
    month = {November},
    year = {2026}
}
Acknowledgements
Write acknowledgements for contributors.